Thousands of concurrent calls
Scale avatar sessions into the thousands, ready for high-volume production workloads.
LemonSlice puts a lifelike, interactive avatar on top of the speech models you serve on Baseten. Whether you run Whisper-class STT, open TTS, or fine-tuned checkpoints, the interactive avatar turns that audio into natural, face-to-face conversation.


At a glance
Baseten keeps doing what it does today. LemonSlice turns the audio into a face.
Your open speech models keep running on Baseten exactly as deployed. Model weights, endpoints, and scaling configuration stay untouched.
Point the audio output from your Baseten-served TTS model at the LemonSlice avatar API. The avatar renders in real time with accurate lip sync and expression.
LemonSlice delivers the avatar video over WebRTC, natively via LiveKit, Daily (Pipecat), or Agora. Your users see a responsive face in about the blink of an eye.
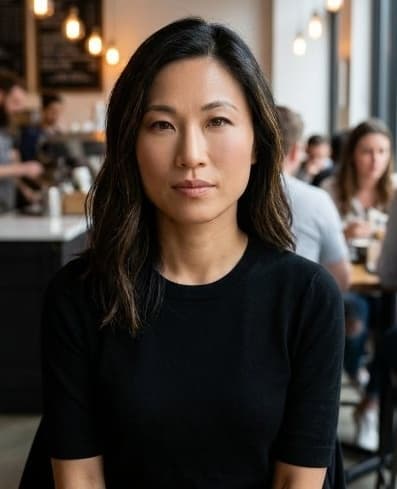
A Baseten session with a LemonSlice avatar.
from livekit import agents
from livekit.agents import AgentSession, RoomOutputOptions
from livekit.plugins import lemonslice

async def entrypoint(ctx: agents.JobContext):
    await ctx.connect()

    session = AgentSession(
        # Add Baseten for TTS and STT, plus your LLM, here
    )

    avatar = lemonslice.AvatarSession(
        # Publicly accessible image URL for the avatar
        agent_image_url="...",
        # Prompt to guide the avatar's demeanor while speaking
        agent_prompt="a person talking",
        # Recommended. Adapts video quality to each viewer's bandwidth
        simulcast=True,
    )

    # Start the avatar and wait for it to join
    session_id = await avatar.start(session, room=ctx.room)

    # Start your agent session with the user
    await session.start(
        # ... room, agent, room_options, etc....
)The Action Engine moves face, hands, shoulders, and posture together. You trigger actions and emotions from the API, down to a prompt like "talk with hand gestures."
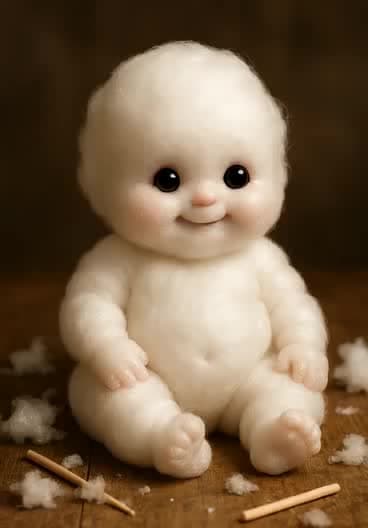
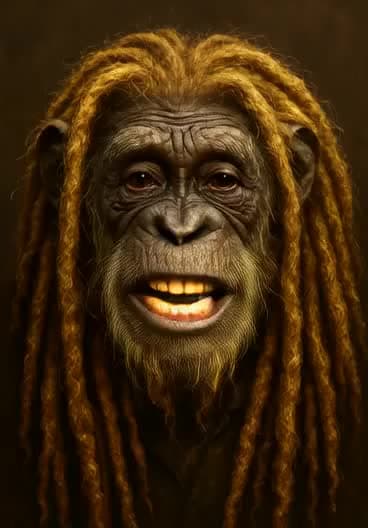
LemonSlice is the only avatar model that brings non-humans to life, a turtle or a smiling teacup, with the same ease as cartoons and photorealistic people.
LemonSlice leads every major avatar provider on response time, so replies feel instant.
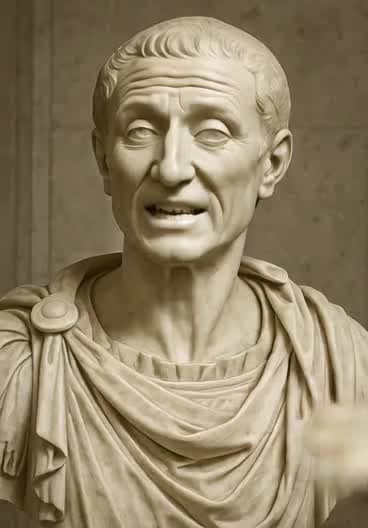
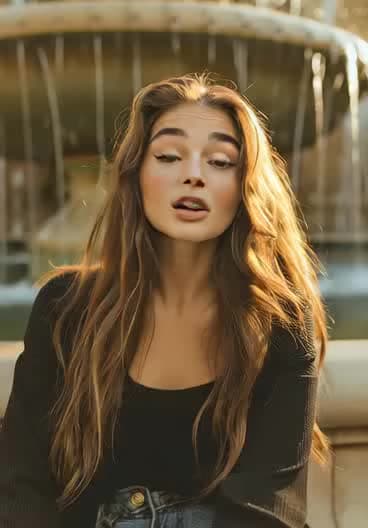
Turn any image into an interactive avatar. No training or fine-tuning needed. Make unlimited custom characters and change outfits or settings in real time.
Avatar sessions alongside Baseten run at production scale.
Thousands of concurrent calls
Scale avatar sessions into the thousands, ready for high-volume production workloads.

Multi-region servers
Place avatar sessions in the region nearest your users so latency stays minimal.

Zero data retention mode
Store no conversation data during avatar sessions, made for privacy-sensitive enterprise workflows.
Create avatars for everything from language practice to customer support, live streaming, and airport kiosks.
Stream audio from models served on Simplismart into a lifelike real-time avatar for face-to-face conversation.

Pair NVIDIA Riva and NIM speech pipelines with a real-time LemonSlice avatar that speaks every response.
The LemonSlice avatar joins your LiveKit room as a participant and gives your voice agent a real-time face.
Stream your model's audio into a live avatar with a 5-minute API setup.